Most teams start GEO the same way they started SEO: they take the keyword list they already have and treat it as the prompt list too. It's a reasonable first move, and a wrong one to stop at. A person typing "CRM" into Google and a person asking ChatGPT "what CRM should a five person startup use if we're already on Notion and Slack" are doing the same job, but the second query carries far more context, and AI systems do a lot more with that context than a search engine ever did with a keyword.
What actually happens after someone hits enter
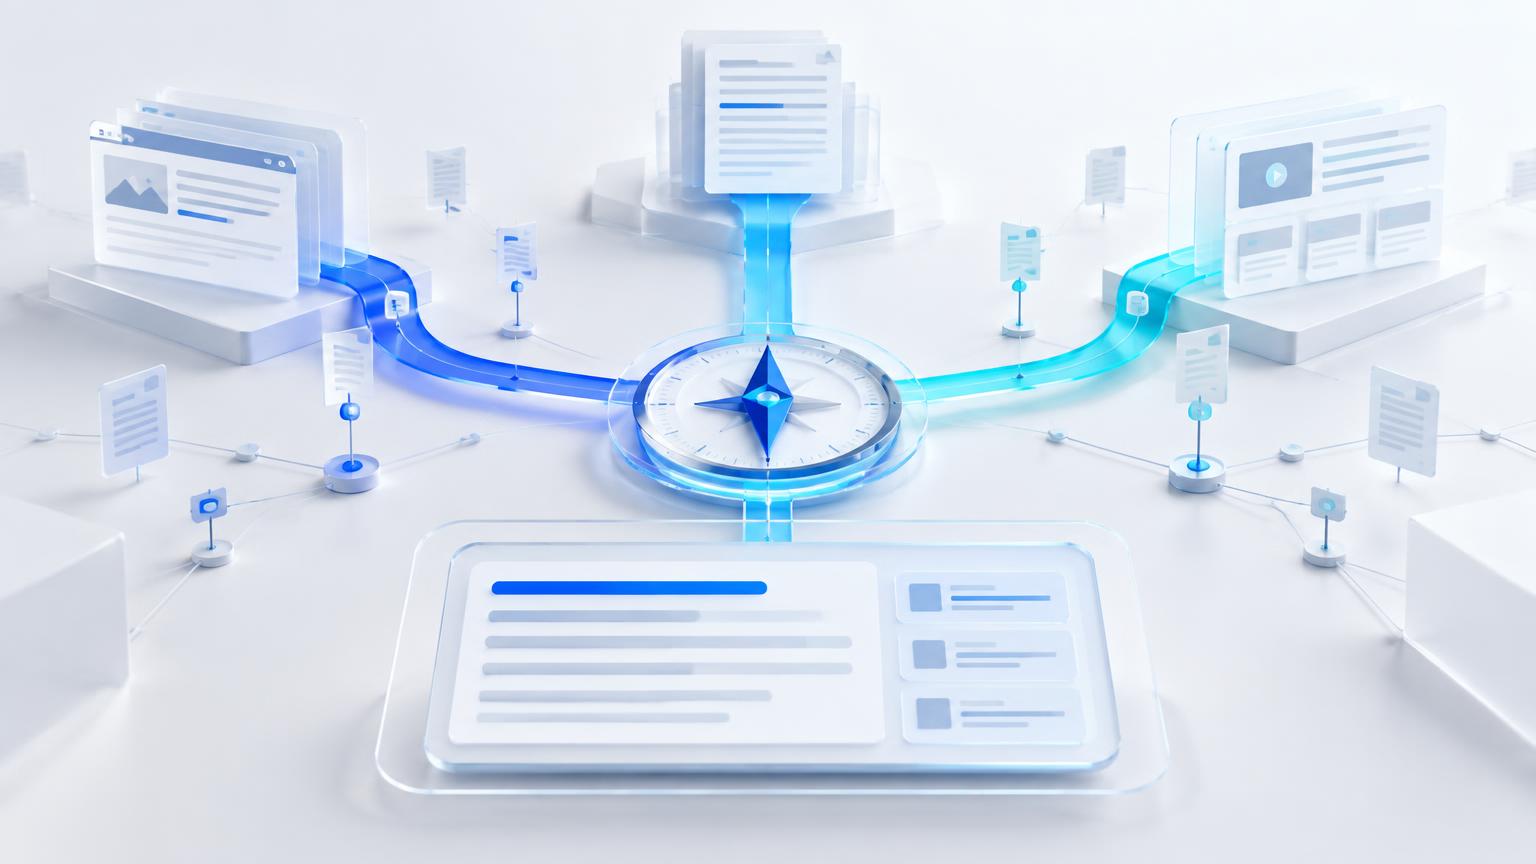
When a person asks ChatGPT, Perplexity or Google's AI Mode a question, the system rarely searches for the literal sentence they typed. It breaks the question into a handful of related sub-queries, runs them at the same time, and stitches the strongest passages from all of them into one answer. Researchers call this query fan-out, and it's the single biggest reason a page can rank well in classic search and still never get mentioned in an AI answer.
Independent analysis of ChatGPT's query fan-out behavior has found the single most common word the model injects into its hidden searches, even when the person never typed it, is "best." Other frequent additions are top, comparison, reviews, and the current year.1 ChatGPT then blends the results from all those hidden searches using an algorithm called Reciprocal Rank Fusion, a retrieval-ranking method (first published in 2009 and widely used across search systems) that scores content appearing across multiple fan-out searches more highly than content that only surfaces for one.2 That combination explains a lot about why "best of" listicles keep winning AI citations even for people who never asked for a ranked list, and why appearing in just one of the sub-query results usually isn't enough.
That last number is worth sitting with. If the sources ChatGPT cites for a query barely overlap with what Perplexity or Google AI Mode cite for the same question, tracking "your visibility in AI search" as one number was never going to be accurate. It has to be tracked per engine.
Why sampling a prompt once isn't enough
Before getting into where to find prompts, it's worth addressing a problem that undermines prompt research even when you've found the right questions: these models are probabilistic. Ask the same question twice and you can get two different citation outcomes, not because anything changed, but because of randomness baked into how the model samples and ranks sources.
Independent audience-research firm SparkToro tested this directly: when they ran the same brand-recommendation prompt through ChatGPT 100 times, the model returned the exact same list of brands in fewer than 1 out of 100 responses.6 Separately, Ahrefs' analysis of AI Overview responses found the cited sources changed entirely for 70% of identical, repeated queries, with an average of 45.5% of citations replaced by different sources between one response and the next.7 In other words, a single test run of "what's the best running shoe for flat feet" tells you almost nothing reliable about who actually gets cited, since the next run is likely to look meaningfully different even though nothing about the underlying pages changed. Industry guidance built on this same statistical reality generally recommends somewhere in the range of 60 to 100 repeated runs per prompt to get a workable margin of error, similar to the sample sizes a serious opinion poll would use.8
The practical implication for prompt discovery specifically: once you've identified a candidate prompt worth tracking, don't judge whether you're "winning" or "losing" it off one or two checks. Run it repeatedly over at least several days before drawing a conclusion, and expect the specific cited sources to shift somewhat between runs even when your own content hasn't changed at all.
How the major engines fan out differently
| Engine | Typical fan-out | What it favors |
|---|---|---|
| ChatGPT | Roughly 2–3 searches for a software or product query; triggers a live web search on about 3 in 10 prompts | Injects "best," "reviews," and the current year even when the user didn't ask; leans on ranked-list style sources9 |
| Perplexity | Cites 3–8 sources per answer | Source diversity and recency, across multiple content types rather than one dominant format9 |
| Google AI Mode / AI Overviews | 8–12 sub-queries via a dedicated Gemini model | Passage-level retrieval, meaning it can cite one paragraph of a page rather than the page as a whole3 |
| Gemini (standalone) | 10.7 fan-out queries on average | Broad topic coverage across a wider question set than a single-answer engine4 |
Figures come from independent studies with different sample sizes and methods, so treat the exact numbers as directional. The pattern across all of them holds: every major engine fans a question out into several searches, and no two engines fan it out the same way.
Worth spending a moment on each of these individually, since "fan-out" hides real behavioral differences a tracking strategy needs to account for.
ChatGPT is the most selective about when it bothers to search the live web at all, roughly three in ten prompts trigger a search, with the rest answered from its training data alone. When it does search, it tends to inject commercial, ranking-flavored language into its hidden queries even for neutral-sounding prompts, which is part of why comparison and "best of" content performs disproportionately well on this engine specifically.
Perplexity behaves more like a research assistant than a search engine: it consistently pulls from several sources per answer and shows a stronger preference for recently published content across a mix of formats, rather than converging on one dominant content type the way ChatGPT leans toward listicles.
Google's AI Mode and AI Overviews run the deepest fan-out of the group, generating roughly eight to twelve sub-queries through a dedicated retrieval model, and critically, they retrieve at the passage level. That means a single well-structured paragraph deep inside an otherwise average page can get cited, even if the page as a whole wouldn't rank well in classic search.
Standalone Gemini sits at the high end of fan-out depth too, averaging 10.7 sub-queries per prompt, suggesting it casts an even wider net across a topic than a narrower, answer-focused engine would.
More words means more implied sub-questions for a model to chase down, and more surface area for your content to either match or miss. This is why a keyword list, even a good one, runs out of runway fast once you're trying to track AI visibility properly.
Not every prompt is worth tracking
The instinct once teams realize this is to track everything: every phrasing, every variant, every fan-out. That's the wrong instinct. An analysis of more than 100,000 tracked prompts found that roughly 80% of brand citations came from just 20% of the prompts being tracked.11 Most of what gets monitored is noise. The job is finding the 20% early rather than discovering it by accident six months in.
A scoring framework for prioritizing prompts
Once you've generated a long candidate list using the methods below, you need a way to cut it down. A simple three-factor score works well: rate each candidate prompt 1 to 5 on buying intent (is this close to an actual purchase decision, or just general curiosity), estimated frequency (how often is a real person likely asking some version of this, even without hard volume data), and winnability (do you have a realistic shot at being cited here today, or is a much larger competitor already dominant). Multiply the three, and prioritize the prompts that score highest, not the ones that simply sound most important.
| Example prompt | Buying intent | Frequency | Winnability | Priority score |
|---|---|---|---|---|
| "which CRM is best for a 5-person startup?" | 5 | 4 | 4 | 80 |
| "what is customer relationship management?" | 1 | 5 | 3 | 15 |
| "is [our brand] better than [market leader] for enterprise?" | 5 | 2 | 1 | 10 |
| "how do I migrate from a spreadsheet to a CRM?" | 4 | 3 | 4 | 48 |
Scores are illustrative. The point of the exercise is comparative, ranking your own candidate list against itself, not arriving at an absolute number that means anything outside your own tracking set.
Eight ways researchers actually find these prompts
None of these methods are exotic. What matters is running several of them together, since each one surfaces a different slice of how people actually talk to AI.
- 01Expand your existing keywords into natural languageTake your highest-value keywords and rewrite them the way a person would actually ask a question out loud, with context attached: not "best CRM," but "best CRM for a five person startup already using Slack."
- 02Mine People Also Ask and AI Overview triggers PAABoth are made of real related questions Google already associates with your topic. They translate almost directly into prompt phrasing, and they're free to pull.
- 03Ask the models what people ask themPrompting ChatGPT or Perplexity directly with "what questions do people typically ask about [your category]" surfaces phrasing patterns you wouldn't have guessed, straight from the source.
- 04Read Reddit and Quora Reddit QuoraThis is where a lot of AI training and retrieval data actually comes from. The way people phrase a complaint or a comparison on Reddit tends to resemble how they'll phrase it to ChatGPT a week later.
- 05Walk your own product line, feature by featureFor every core feature, service or use case you sell, write the two or three questions a buyer evaluating that specific thing would ask. This tends to surface the prompts closest to actual revenue, not just topic relevance.
- 06Watch which fan-outs your competitors keep showing up in Fan-outRun your own head-term prompts, note the sub-queries a model generates behind them, and check which of those sub-queries a competitor already owns. Those gaps are usually the fastest wins.
- 07Mine your own sales calls and support ticketsThe exact phrasing a prospect used on a discovery call, or a confused customer used in a support ticket, is often closer to how they'd phrase a prompt than anything in a keyword tool. This source is free and almost always underused.
- 08Compare branded vs. non-branded query patterns in Search ConsoleA spike in non-branded, comparison-flavored queries ("alternative to," "vs," "for [use case]") in your existing search data often mirrors the exact way people phrase the equivalent AI prompt.
Cover the five ways people actually phrase a question
Researchers studying prompt behavior generally group prompts into five intents. A healthy tracking list has a mix of all five, not just the obvious one.
| Type | What it sounds like |
|---|---|
| Informational | "How does an AI visibility tool actually work?" |
| Comparative | "Ripplix vs a traditional SEO platform for AI visibility" |
| Instructional | "How do I improve my brand's citation rate in ChatGPT?" |
| Brand or product specific | "Does Ripplix track Perplexity as well as ChatGPT?" |
| Evaluative | "Is it worth switching from a rankings dashboard to an AI visibility tool?" |
Adapted from prompt category research by AccuRanker.12 Most brands over-index on informational and under-track comparative and evaluative prompts, even though those two carry the most buying intent.
A worked example, start to finish
Say you run a CRM built for small sales teams, call it Optra, competing against a handful of similar tools. Here's how the methods above stack together in practice, rather than being used one at a time in isolation.
Start with the keyword list: "CRM for startups," "CRM pricing," "best sales CRM." Expand each into natural phrasing: "what CRM should a five person startup use," "is Optra worth the price for a small team," "best sales CRM under $50 a month." Pull PAA questions from a Google search on "best CRM for small business" and you'll likely surface variants like "what is the easiest CRM to learn" or "do I need a CRM if I only have 10 customers." Read r/startups and r/sales on Reddit for threads discussing CRM choice, which typically surface phrasing like "is Optra better than [competitor] for early-stage companies" almost verbatim, since that's exactly how people ask each other, not just AI. Ask ChatGPT directly what questions people ask about choosing a CRM, and cross-reference the answer against what you've already found, to catch anything missed. Walk the product line: for an integrations feature, that's "what CRM has the best API for developers" or "Optra vs [competitor] for Slack and Notion integrations." Check competitor fan-outs by running "best CRM for small business" yourself and noting which sub-queries a competitor already dominates, such as "CRM migration from spreadsheet," which might reveal an onboarding-content gap. Finally, score the resulting list using the priority framework above, and you'll typically find the highest-scoring prompts cluster around buying-decision and integration questions, not the generic informational ones that felt most obvious at the start.
Then treat the list as a living thing, not a one-time export
Fan-out behavior shifts as models get updated, and the phrasing people use shifts with the season, the news cycle and whatever your competitors just launched. A prompt list built once in January and left untouched will quietly go stale. The teams that stay ahead treat prompt discovery the same way they'd treat keyword research a decade ago: an ongoing habit, not a one-time project.
Common mistakes in prompt discovery
- 01Reusing the SEO keyword list unchangedA keyword and a prompt are different objects. Rewriting into natural, context-rich phrasing is not optional, it's the whole point.
- 02Judging visibility off a single prompt runAs the sampling research above shows, one run can return a meaningfully different list of cited sources than the next. Sample repeatedly before concluding anything.
- 03Tracking only informational promptsThey're the easiest to think of and usually the lowest in buying intent. Comparative and evaluative prompts convert better and get tracked less.
- 04Never revisiting the listFan-out patterns and buyer phrasing both drift over time. A list that was right six months ago is quietly going stale right now.
Skip the guesswork
Ripplix's Prompt Discovery surfaces the real questions your buyers ask across Reddit, Quora, People Also Ask and AI fan-out data, then clusters them into themes you can actually track.
Get your free AI Visibility Report →- Independent analysis of ChatGPT query fan-out word-injection patterns, reported via Neil Patel, 2026.
- Analysis of ChatGPT's Reciprocal Rank Fusion retrieval mechanism, cited via Discovered Labs, 2026; RRF itself originates from Cormack, Clarke & Buettcher, 2009.
- Google AI Mode technical guidance and independent fan-out analyses, 2025–2026.
- Independent measurement of Gemini fan-out depth, cited via SEER Interactive.
- Cross-platform citation overlap analysis, Topify, 2026.
- SparkToro / Gumshoe Research, repeated-prompt brand recommendation study on ChatGPT, 2026.
- Ahrefs, analysis of AI Overview citation turnover across repeated identical queries, 2025.
- SparkToro sampling-depth recommendation, cited via Search Engine Journal, 2026.
- Tripledart query fan-out research across ChatGPT and Perplexity, 2026.
- iPullRank query length analysis, via AirOps.
- Texta, analysis of 100,000+ tracked prompts.
- AccuRanker, prompt category research, 2025.